Building Your First Neural Network with Python
Neural networks have become a foundational tool in modern machine learning, enabling systems to learn from data in ways that mimic certain aspects of biological learning. For those new to this field, building a first neural network can seem like a complex task, but modern libraries such as Keras simplify the process considerably. This article provides a process-oriented guide to constructing a simple neural network using Python and Keras, focusing on the steps of model design, compilation, and training. The goal is to explain the methodology behind each step, allowing you to understand how the components work together, without making any promises about specific outcomes. Whether you are a student, a data enthusiast, or a professional exploring machine learning, this tutorial offers a clear path to get started.
The approach taken here is intentionally minimalist, using a small dataset and a straightforward architecture to illustrate the core concepts. By the end, you will have a functional neural network model that can be trained on data, and you will be equipped with the knowledge to modify and extend it for more complex problems. The steps outlined are meant to be reproducible, and the code snippets are designed to run in a standard Python environment with Keras installed. It is important to note that the success of a neural network depends on various factors, including data quality, architecture choices, and training parameters, and this tutorial does not guarantee any particular performance level.
Understanding Neural Network Fundamentals
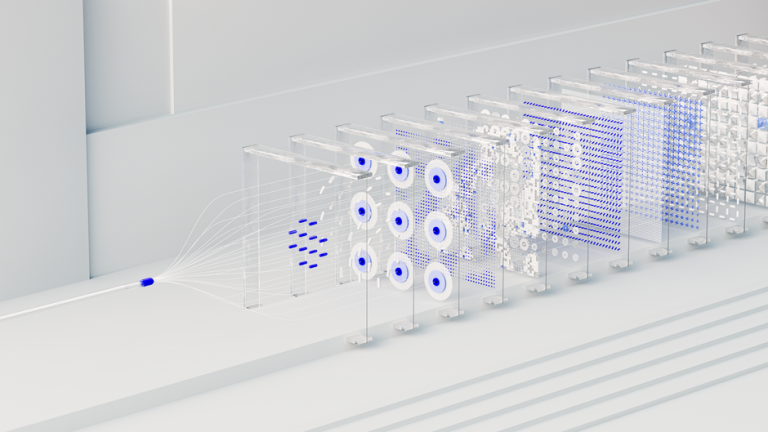
Before diving into code, it is helpful to review what a neural network is and how it operates. At its core, a neural network consists of layers of interconnected nodes, or neurons, that process input data and produce an output. Each connection has a weight, and each neuron applies an activation function to the weighted sum of its inputs. The network learns by adjusting these weights based on the error between its predictions and the actual targets, a process known as backpropagation. This learning is guided by an optimization algorithm, such as stochastic gradient descent, which iteratively updates the weights to minimize a loss function.
In practice, a neural network is defined by its architecture, which includes the number of layers, the number of neurons in each layer, and the activation functions used. For simple problems, a model with one hidden layer may suffice, while more complex tasks often require deeper architectures. The choice of activation function affects how the network can capture non-linear relationships; common options include ReLU, sigmoid, and softmax. Understanding these components is essential for designing a network that can learn from data effectively.
Keras, now part of TensorFlow, provides a high-level API that abstracts away much of the underlying complexity. It allows you to define models in a simple, sequential manner, stacking layers as needed. This design makes it an ideal choice for beginners, as it focuses on the logical flow of building a network rather than getting bogged down in implementation details.
Setting Up the Environment and Data
The first concrete step is to ensure that your Python environment has the necessary libraries installed. This tutorial uses Keras with a TensorFlow backend, so you will need to install both. Using a package manager like pip, you can install TensorFlow, which includes Keras as a built-in module. It is also recommended to use a virtual environment to avoid conflicts with other projects. Once the installation is complete, you can import the required modules: tensorflow for the backend, and keras for the high-level API. In addition, you may need numpy for numerical operations, and matplotlib if you wish to visualize the training process.
For demonstration, we will use a simple dataset: the classic Iris dataset, which contains measurements of iris flowers and their species. This dataset is often used for classification tasks and is available in many libraries, including sklearn. However, to keep the tutorial self-contained, we can generate a synthetic dataset using make_classification from scikit-learn. This dataset will have a manageable number of features and classes, making it suitable for a first neural network. The data is then split into training and test sets, with the training set used to fit the model and the test set used to evaluate its performance after training.
Before feeding the data into the network, it is good practice to preprocess it. Features should be scaled to a similar range, often using standardization (zero mean, unit variance) or normalization (scaling to [0,1]). This can help the optimization converge faster and avoid issues with large numerical values. Keras provides utilities for preprocessing, but for simplicity, we can use scikit-learn’s StandardScaler. Additionally, the target labels may need to be converted to a format suitable for training, such as one-hot encoding for multi-class classification.
Designing the Network Architecture
With the data ready, the next step is to define the architecture of the neural network. In Keras, this is typically done using the Sequential model, which allows you to add layers one by one. The first layer must specify the input shape, which corresponds to the number of features in the dataset. For our example, we will have four features, so we set input_dim=4. The architecture will consist of a hidden layer with a certain number of neurons and an output layer. The hidden layer uses an activation function like ReLU to introduce non-linearity, while the output layer uses softmax if we are performing multi-class classification, providing a probability distribution over classes.
The number of neurons in the hidden layer is a hyperparameter that can be tuned. For a simple problem, a layer with 8 or 16 neurons is often sufficient. It is important to note that while more neurons can capture more complex patterns, they also increase the risk of overfitting, especially with limited data. Overfitting occurs when the model learns the training data too well, including its noise, but fails to generalize to new data. To mitigate this, you can incorporate regularization techniques, such as dropout, which randomly drops a proportion of neurons during training to force the network to learn more robust features.
Here is the code snippet for building the model:
from tensorflow.keras.models import Sequential
from tensorflow.keras.layers import Dense, Dropout

model = Sequential([
    Dense(8, activation='relu', input_shape=(4,)),
    Dropout(0.2),
    Dense(3, activation='softmax')
])
Choosing the right number of neurons and layers is not an exact science; it often requires experimentation. Starting with a small model and gradually increasing complexity is a reasonable strategy to understand the impact of each change.
Compiling and Training the Model
After defining the architecture, the model must be compiled to configure the learning process. Compilation involves specifying the optimizer, the loss function, and the metrics to monitor. The optimizer is responsible for updating the weights based on the gradients; common choices include Adam, which adapts the learning rate during training, and stochastic gradient descent (SGD) with momentum. For classification tasks, the categorical cross-entropy loss function is often used, as it measures the difference between the predicted probability distribution and the true distribution. You can also specify a list of metrics, such as accuracy, to track during training.
Training the model involves calling the fit method, which takes the training data, the number of epochs (iterations over the entire dataset), and the batch size (the number of samples used in each update). The validation_split parameter can be used to hold out a portion of the training data for validation, providing insight into how the model performs on unseen data during training. The fit method returns a history object that contains the loss and metrics for each epoch, which can be used to plot learning curves.
Here is an example:
model.compile(optimizer='adam', loss='categorical_crossentropy', metrics=['accuracy'])
history = model.fit(X_train, y_train, epochs=50, batch_size=8, validation_split=0.2)
The training process is iterative: the model makes predictions, calculates the loss, computes gradients for each weight, and updates them to minimize the loss. The number of epochs should be chosen carefully: too few may result in underfitting, while too many may lead to overfitting. Early stopping is a technique that can automatically stop training when the validation loss stops improving, which can help prevent overfitting.
Evaluating and Improving the Model
Once training is complete, the next step is to evaluate the model’s performance on the test set, which contains data not used during training. This evaluation provides an estimate of how well the model might perform on new, unseen data. In Keras, you can use the evaluate method to compute the loss and any metrics defined during compilation. For example, test_loss, test_acc = model.evaluate(X_test, y_test) returns the loss and accuracy on the test set. It is important to keep in mind that the results are conditional on the data and the choices made during the design and training phases.
To gain a deeper understanding of the model’s behavior, you can inspect the history object to plot the training and validation loss and accuracy over epochs. These plots can reveal signs of overfitting or underfitting. If the training loss continues to decrease while the validation loss plateaus or increases, it is a sign that the model is overfitting. In such cases, you might consider adding dropout or regularization, reducing the model complexity, or using data augmentation. If the model is underfitting, you could increase the number of neurons, add more layers, or train for more epochs, though it is important to note that these adjustments do not guarantee improvement, as the model’s performance is constrained by the data and the problem at hand.
Additionally, you can experiment with hyperparameters such as the learning rate, batch size, and the optimizer itself. Techniques like grid search or random search can help find a good set of hyperparameters, but they can be computationally expensive. The process of tuning is iterative and context-dependent, and there is no one-size-fits-all approach.
Conclusion and Next Steps
This tutorial has walked through the fundamental steps of building a neural network with Python and Keras, from setting up the environment to evaluating the trained model. Each step—data preparation, architecture design, compilation, training, and evaluation—plays a critical role in the overall process. The modular and high-level nature of Keras allows beginners to focus on the logic and methodology without getting lost in the implementation details. However, it is essential to recognize that the performance of a neural network is influenced by numerous factors, including the quality of the data, the appropriateness of the architecture, and the choice of training parameters. The outcome of training is never guaranteed, and results should be interpreted within the context of the specific problem.
As you continue to explore neural networks, you can build on this foundation by experimenting with different types of layers (e.g., convolutional for images), more complex architectures, and advanced training techniques such as learning rate schedules and regularization. The field is vast, and continuous learning and experimentation are key to developing a deeper understanding. Remember that every model is a simplification of reality, and its success depends on how well it captures the underlying patterns in the data for the task at hand.